前些天发现了一个巨牛的人工智能学习网站,通俗易懂,风趣幽默,忍不住给大家分享一下。点击跳转到网站:https://www.captainai.net/dongkelun
前言
记录总结一下 Hive 表如何添加新的字段以及遇到的问题。
最初是因为要验证 Hudi Schema Evolution 中的增加字段问题
SQL
1 | alter table test_hive add columns (col_new string); |
示例
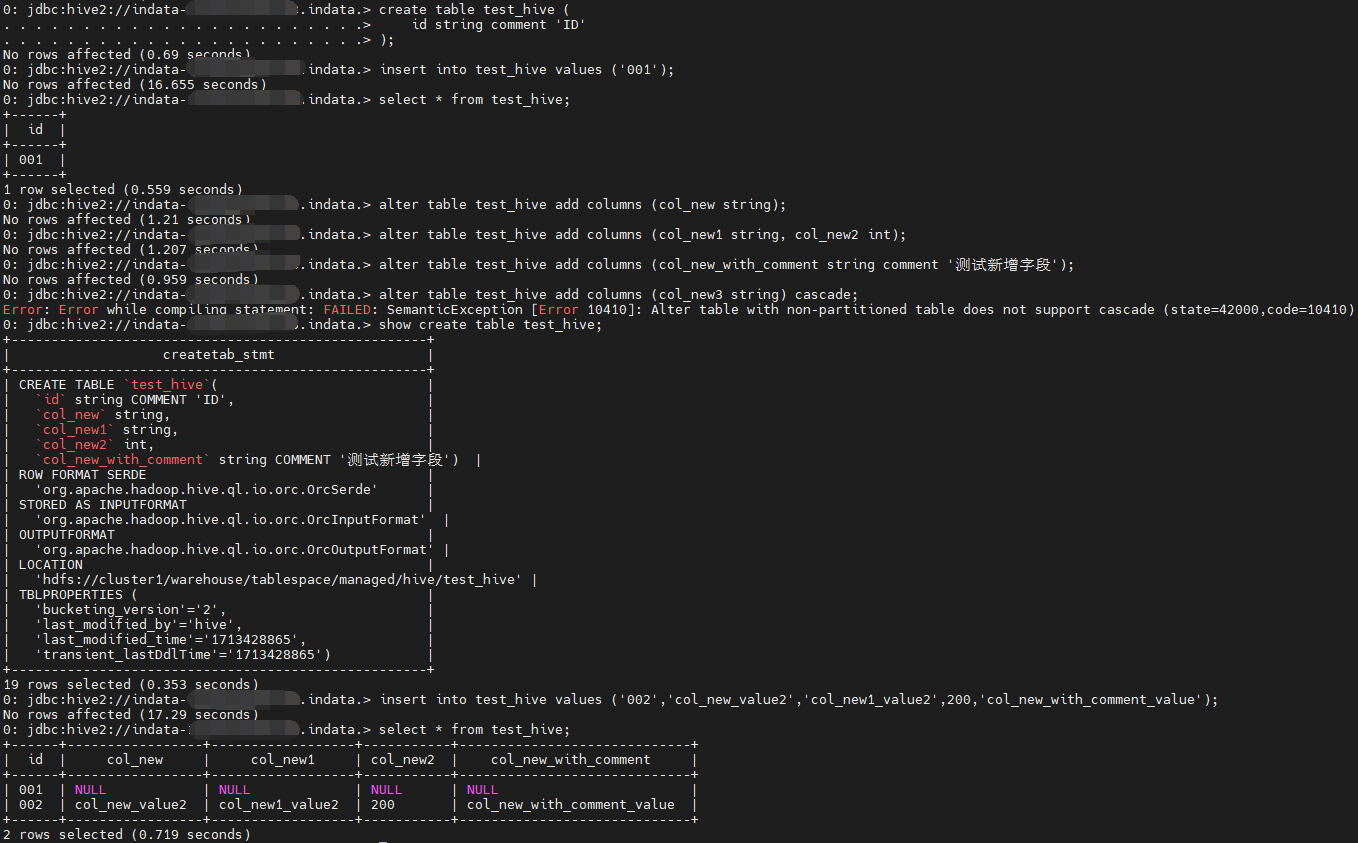
建表
1 | create table test_hive ( |
插入数据
1 | insert into test_hive values ('001'); |
查询
1 | select * from test_hive; |
新增几个字段
1 | alter table test_hive add columns (col_new string); |
查看表结构
1 | show create table test_hive; |
插入数据
1 | insert into test_hive values ('002','col_new_value2','col_new1_value2',200,'col_new_with_comment_value'); |
查询新增列新增数据是否正常
1 | select * from test_hive; |
问题
如上SQL所述,对于 Parquet、Text 分区表增加字段时如果不加 cascade 会有问题:新增字段后,对于已存在的分区新增的数据,新增字段查询结果为null(Hive查询),用 Spark SQL 和 Flink SQL 查询正常,对应的 parquet文件实际是有数据的。新增分区对应的新增数据,查询结果正常。
问题复现
ORC 分区表
ORC 分区表不存在这个问题
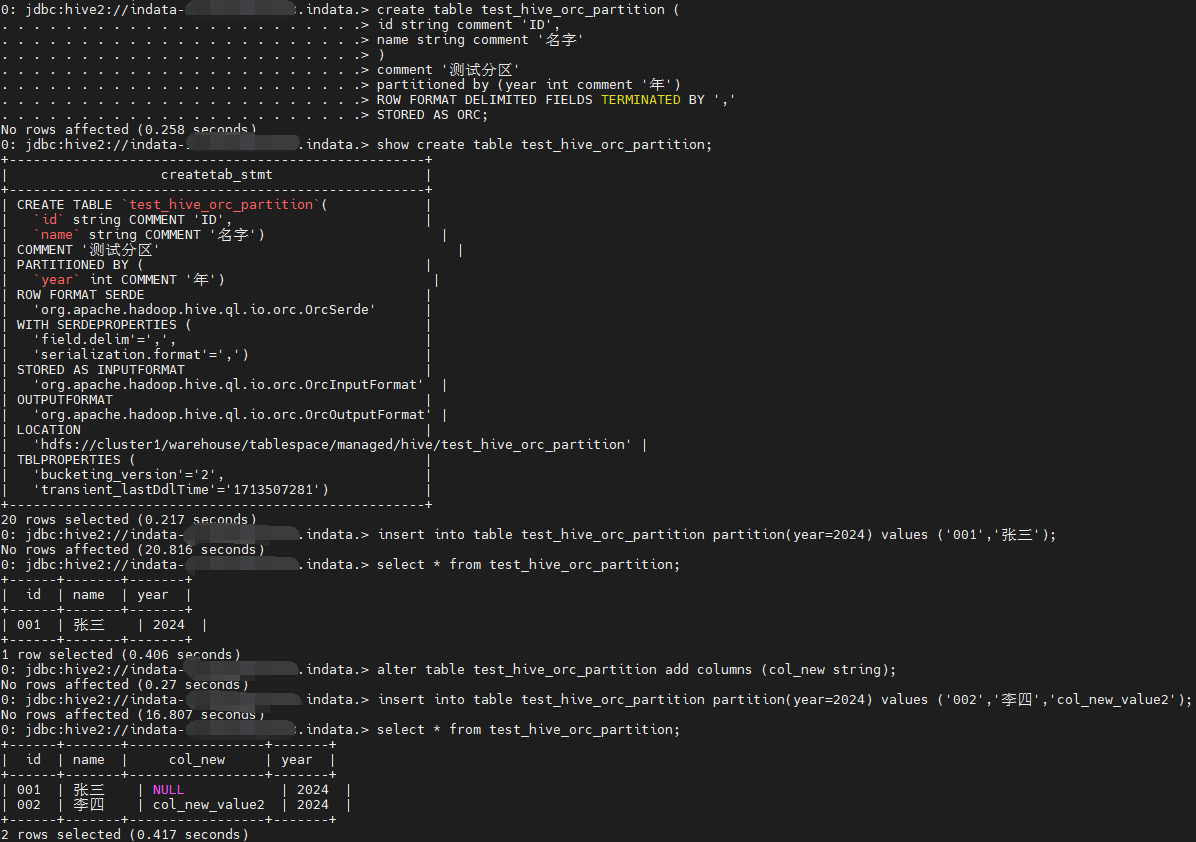
建表
1 | create table test_hive_orc_partition ( |
1 | show create table test_hive_orc_partition; |
插入数据
1 | insert into table test_hive_orc_partition partition(year=2024) values ('001','张三'); |
查询
1 | select * from test_hive_orc_partition; |
新增字段
1 | alter table test_hive_orc_partition add columns (col_new string); |
插入数据
1 | insert into table test_hive_orc_partition partition(year=2024) values ('002','李四','col_new_value2'); |
查询新增列新增数据是否正常
1 | select * from test_hive_orc_partition; |
可以看到一切正常:
Text 分区表
建表
1 | create table test_hive_text_partition ( |
插入数据
1 | insert into table test_hive_text_partition partition(year=2024) values ('001','张三'); |
查询
1 | select * from test_hive_text_partition; |
新增字段
1 | alter table test_hive_text_partition add columns (col_new string); |
插入数据
1 | # 已有分区 |
查询新增列新增数据是否正常
1 | select * from test_hive_text_partition; |
可以看到新增字段对应的查询内容为空:
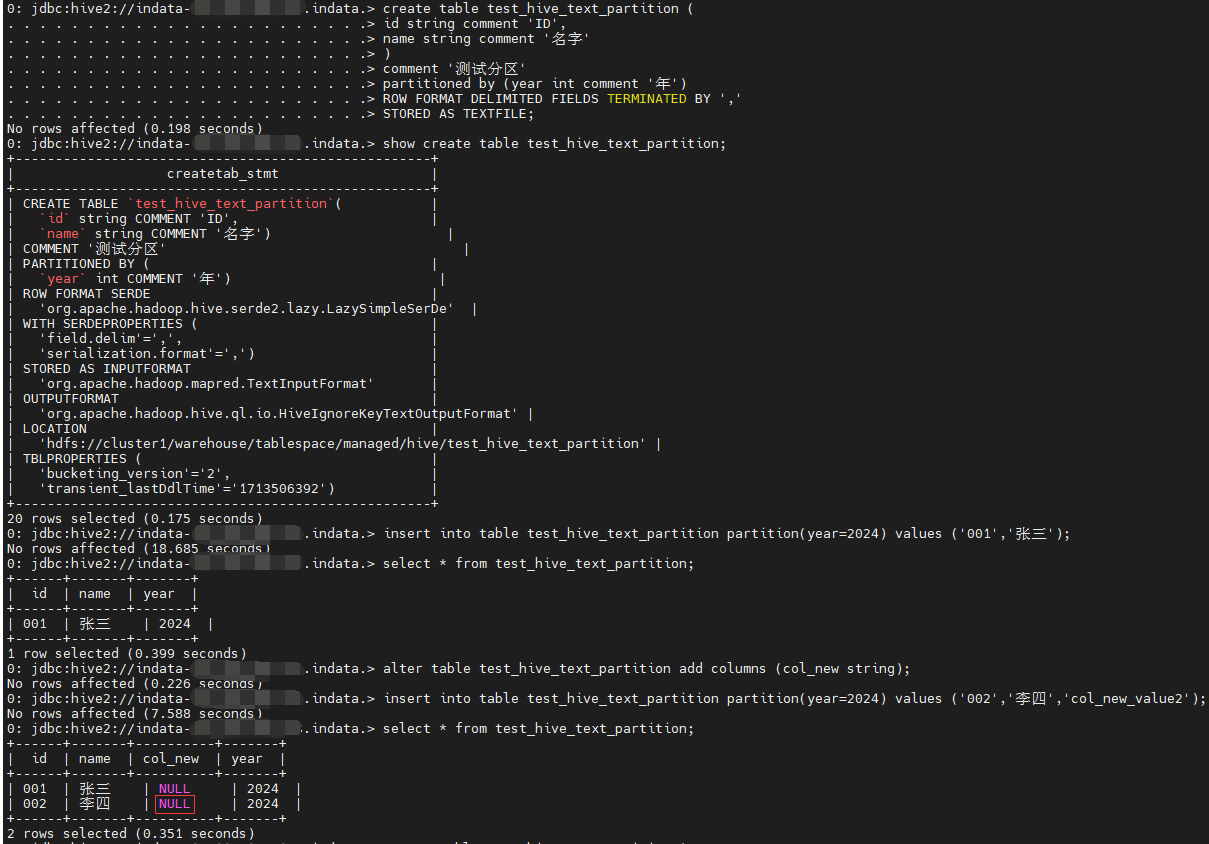
但是对应的数据文件实际是有内容的: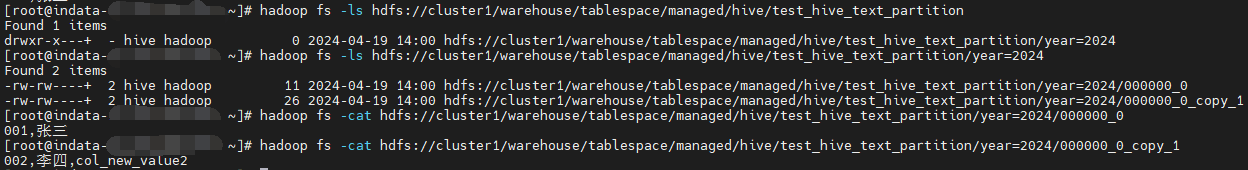
Parquet 分区表
建表
1 | create table test_hive_parquet_partition ( |
插入数据
1 | insert into table test_hive_parquet_partition partition(year=2024) values ('001','张三'); |
查询
1 | select * from test_hive_parquet_partition; |
新增字段
1 | alter table test_hive_parquet_partition add columns (col_new string); |
插入数据
1 | # 已有分区 |
查询新增列新增数据是否正常
1 | select * from test_hive_parquet_partition; |
可以看到对于已有分区新增字段对应的内容为空,新增分区新增字段对应的内容正常。
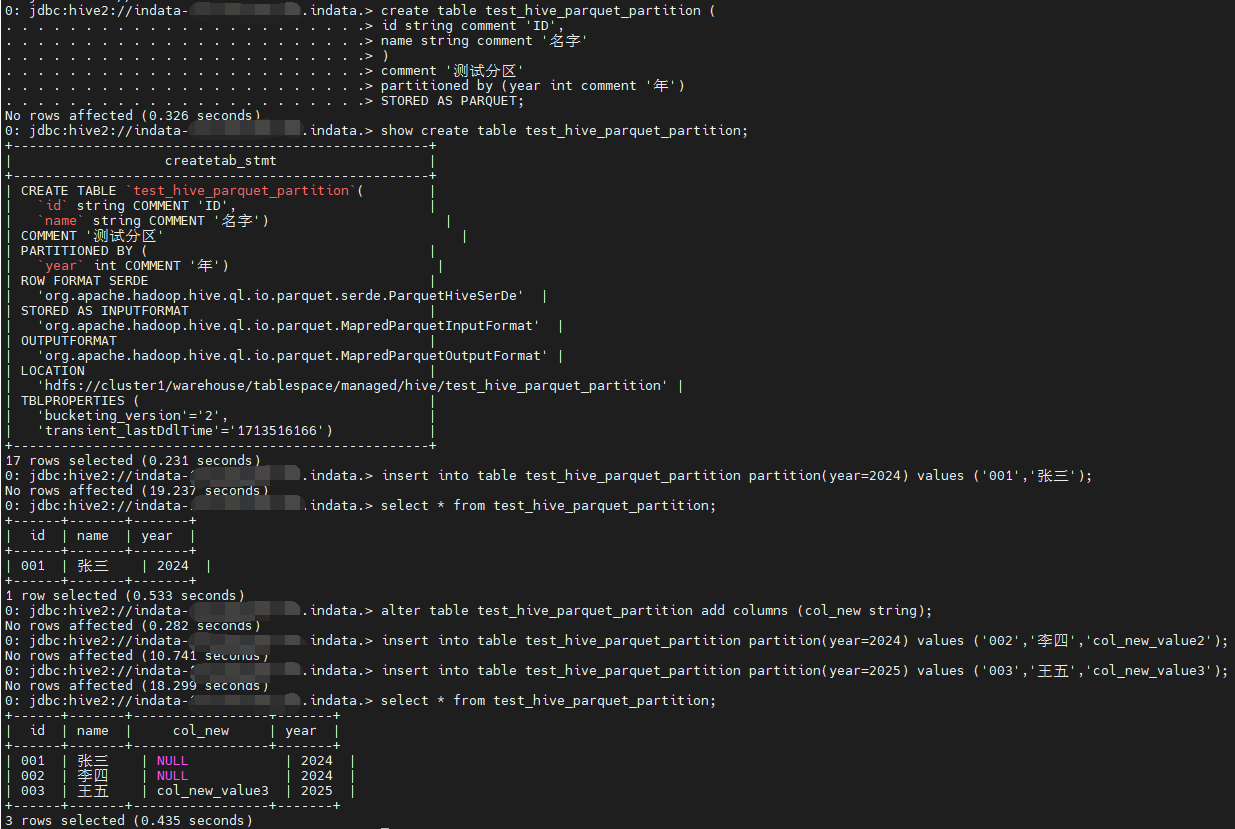
对应的parquet文件新增字段也不为空
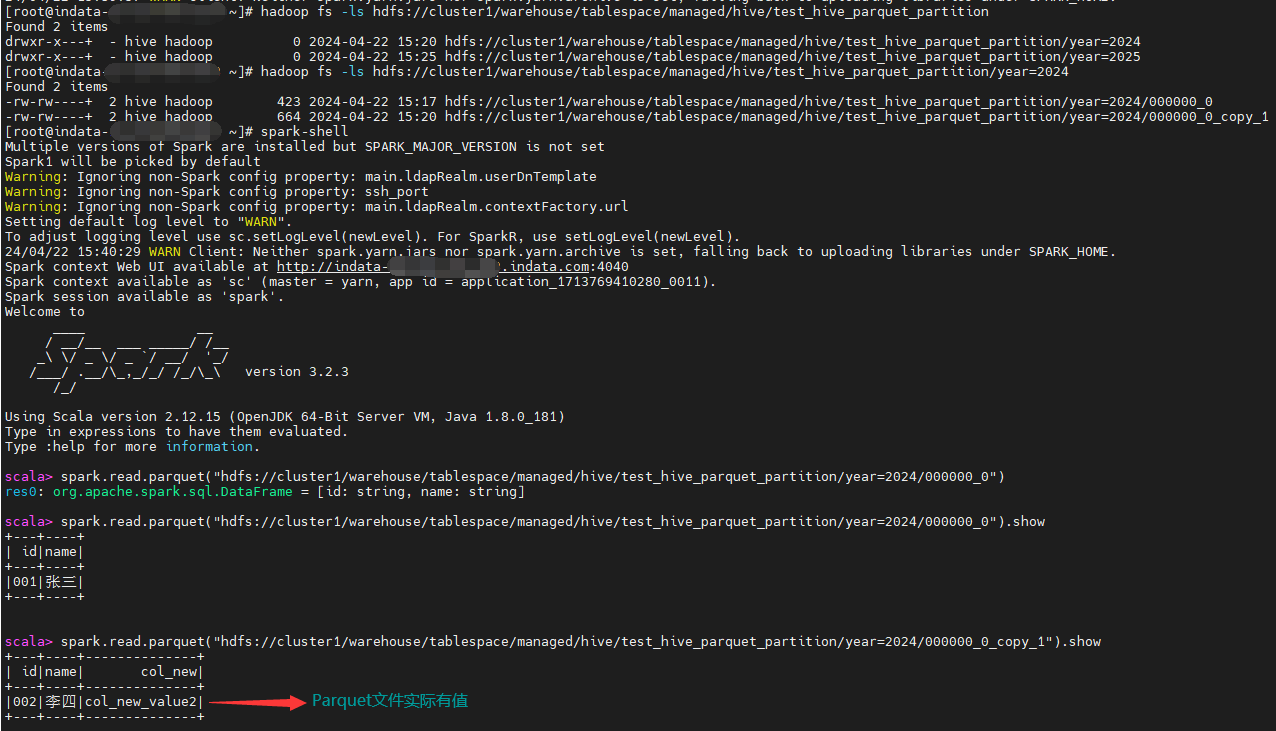
问题总结
对于某些文件类型,如ORC不存在该问题,而对于 Parquet、Text ,只有在已有分区下插入数据时,新增字段查询才为 NULL, 新增的分区正常。
问题解决
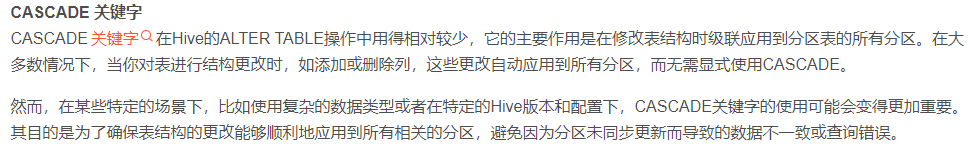
1、新增字段时添加 cascade 关键字,级联应用到分区表的所有分区
1 | alter table test_hive_parquet_partition add columns (col_new string) cascade; |
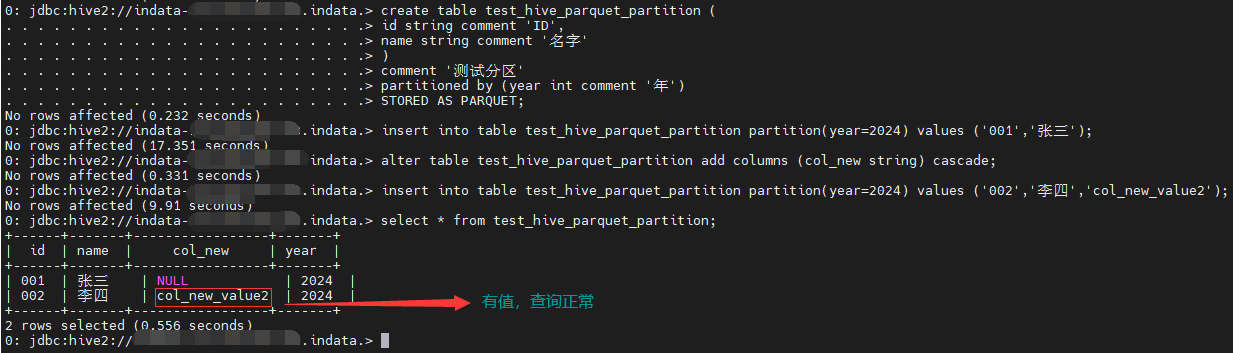
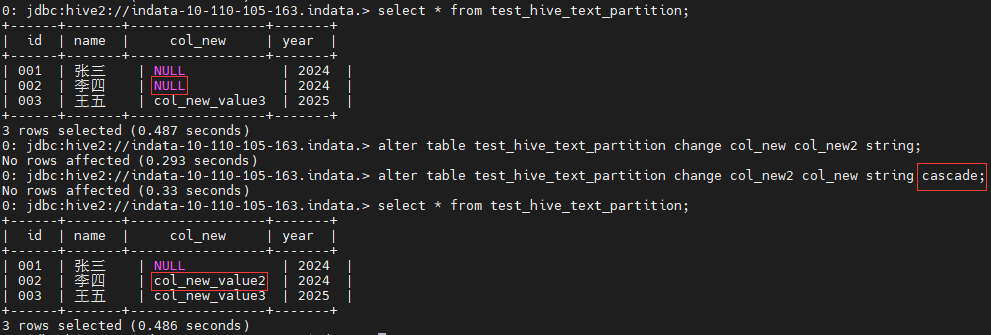
2、如果新增字段时忘了添加 cascade ,则可以通过改名的方式解决。
1 |
|
CASCADE
仅供参考
参考
- https://baijiahao.baidu.com/s?id=1724926871601854322&wfr=spider&for=pc
- https://blog.csdn.net/MyNameIsWangYi/article/details/136022818
相关阅读
本文由 董可伦 发表于 伦少的博客 ,采用署名-非商业性使用-禁止演绎 3.0进行许可。
非商业转载请注明作者及出处。商业转载请联系作者本人。
本文标题:Hive 表添加列(新增字段)
本文链接:https://dongkelun.com/2024/04/22/hive/hiveAddColumns/
欢迎关注我的公众号